MIDREAL
Menu

GPT‑6.2 Astra and Sol

https://openai.com/index/introducing-gpt-6-2-astra-sol/ (openai.com)

1326 points | 4d ago | Discuss on Hacker News | Back to Radar

Comments

ex1fm3ta 4d ago on HN
I thought OpenAI would drop an awesome model on the day of Anthropic IPO, just to troll them
zarzavat 4d ago on HN
It's actually in OpenAI's interests that Anthropic's IPO is successful.
SomeonesAccount 4d ago on HN
explain?
rose52152 4d ago on HN
If Anthropic is a valuable company, then OpenAI is just as valuable, if not more.
rico735 4d ago on HN
Is it not a Nintendo vs Sega situation?

They are too similar for both to win, and the current cost of competition is unsustainable.

zarzavat 4d ago on HN
OpenAI is doing an IPO too. Both Anthropic and OpenAI need to raise money.

Investors will look at Anthropic's IPO as a proxy for how OpenAI's IPO may go. The markets are increasingly sceptical about AI companies, so OpenAI really needs Anthropic's IPO to be a roaring success.

deathtrader666 4d ago on HN
Waiting for the pelicans benchmark.
foolserrandboy 4d ago on HN
With the red scarf and fish in the front basket...
Ersho 4d ago on HN
Another wave of Openai just killed ....

Also, is it website very laggy or is it just me?

rolymath 4d ago on HN
It's super laggy if you mess around a bit, play videos, etc.
Aerroon 4d ago on HN
Just like chatgpt website itself. If the bot answers with pictures and rich text the performance of the tab tanks.
rico735 4d ago on HN
It crashed my browser twice.

AGI.

rico735 4d ago on HN
The racing game doesn't load in Firefox and crashed my Chrome after taking about 3 minutes to load. 2/10.
Ersho 3d ago on HN
It was on purpose probably, AGI does not want you to access lol
montenegrohugo 4d ago on HN
Nice 3D effect. Runs surprisingly well even on on brave on my linux pc without hardware acceleration
hmate9 4d ago on HN
Will need to play around with it to get a feel but those benchmarks with those costs look incredible!

It seems like they were saving these for just before ANT's IPO

christianqchung 4d ago on HN
Caught this on my lunch break, their linked system card (https://deploymentsafety.openai.com/gpt-6-2-astra-sol) isn't up yet.
specked-citrus 4d ago on HN
It's up now
bananaflag 4d ago on HN
Is this the Bel model?
wahnfrieden 4d ago on HN
No
matt3210 4d ago on HN
> frontends that look and work better

The website doesn't event show the graphs properly.

mynameisvlad 4d ago on HN
The graphs look fine on my computer. Can you elaborate on what exactly isn't "shown properly"?
finger 4d ago on HN
Unreadable on the phone
mynameisvlad 4d ago on HN
Unreadable how? If it's the width, you can always... turn your phone sideways?
wasabi991011 4d ago on HN
And the slides and other pdfs don't load next pages or alt documents for me
geauxvirtual 4d ago on HN
Website pegs my GPU at 100%. Are they mining for crypto with this announcement?
enjoyyourlife 4d ago on HN
Trying new ways to create distributed systems to train their LLM
charlesabarnes 4d ago on HN
Its been stated often, but I appreciate that OAI is now bringing the topic of conversation to "task completion cost" rather than brute forcing solutions
theanonymousone 4d ago on HN
Happy for the new Sol. It's my workhorse on company account.

But more than that I'm waiting for new Luna. To me it was the game changer that ended "Tokenpocalypse", and is still almost unbeataben in "infinitely using a decent model" use case.

SomeonesAccount 4d ago on HN
I find that Luna tends to misinterpret instructions in READMEs and Agents.mds. Maybe it is something specific about my setup, but I found that Terra is the lowest I can comfortably use on its own (Luna can be driven by larger models in the form of a subagent and it works great for that)
machomaster 4d ago on HN
I tried Luna to make a simple renaming of files in a directory. The prompt was only a few sentences long and instructions were crystal clear (use 'YYYY-MM-DD' ISO date format in the beginning of the file name). Yet, Luna managed to screw up even this simple process. I completely lost my trust in that model, never touching it again.
MrBuddyCasino 4d ago on HN
I used Luna Max a lot, until Deepseek 1017. Then never again.
ariwilson 4d ago on HN
Why not Haiku 5.5? It's substantially smarter than Luna (though more expensive - still cheap though).

(personal benchmark) https://fairbake.dev/signature/agents/haiku-5-5 vs https://fairbake.dev/signature/agents/gpt-6-luna

I've found Luna to be very lazy as well (claiming to have run tests/builds when it hasn't).

esafak 4d ago on HN
That's why it's so token efficient. It is so lazy that I feel like it's taunting me to do the grunt work. I wonder if there is a benchmark for that.
azuanrb 4d ago on HN
> though more expensive

That’s the main difference. It’s smart enough for most of my tasks, but so cheap that I can use it far more than I could before.

ariwilson 4d ago on HN
Yeah, this really depends on your price sensitivity. Opus cost me about $1 in tokens per task while Haiku costs about 4.6 cents and Luna is about 2.5 cents. I guess I prioritize correctness over cost when you're over 10 times cheaper than the model I like to run interactively.
artursapek 4d ago on HN
Haiku consistently underperforms Luna on my internal eval for the project I'm building. Luna is an incredible model for the price
greenavocado 4d ago on HN
I find this incredibly hard to believe. Are you using effort levels less than medium at any point?
artursapek 2d ago on HN
1024 reasoning token budget. is that low?
koyote 4d ago on HN
Luna is extremely lazy and I feel like it's getting lazier.

I mostly use it to cheaply find out why a build failed (saves me about 5-20 minutes as I can have it run in the background).

It used to tell me which commit caused the failure. Now even if I ask it to, it stops well short with something similar to: "Well the logs say there's an error. I couldn't work out why.".

rbehrends 4d ago on HN
Haiku 5.6 is a surprisingly good model (and IME better than Luna), but the price jump at 100k context and the short TTL of Anthropic caches makes it a less interesting choice for interactive use cases where Luna suffices. It is most likely meant for subagents.

Also, for long contexts, Haiku 5.5's direct competitor is probably Terra 6.1; Terra has similar cost per task with longer cache TTL and equal or better capabilities for long contexts.

I think Anthropic's problem is that they could get a lot of price-conscious people on board by making Haiku more attractive to use as a primary model, but then they'd probably lose money by having more people switch from Opus or Sonnet to Haiku.

jpardoe 4d ago on HN
I’d rather it be exactly what it is. Incredibly cheap fast and effective for quick, well scoped tasks. I need a model for that role and it’s perfect. There’s no way you can make it like more capable models without affecting that. The right tools for the right jobs…
rbehrends 3d ago on HN
I think you misunderstand me. The only thing I would like to see changed is changing the context length at which the price jump occurs from something like 100k to 250k or thereabouts. This would be purely a pricing change, no change in the model's capabilities. Obviously, that may not be in Anthropic's interest, so it's not going to happen unless price pressure mounts.
weird-eye-issue 4d ago on HN
> It's substantially smarter than Luna

Not on a few important tasks in our app that I've tested it on

pietz 4d ago on HN
I didn't find overwhelming evidence that Haiku is smarter than Luna. It's just that the reasoning levels are calibrated very differently. Try running Luna at high or xhigh and see how that closes the gap to Haiku, while probably still being cheaper. Luna is one of the very few models where max reasoning has great value too. Claude's max reasoning is basically just the benchmark tier at this point. Nobody should use it.
nextaccountic 4d ago on HN
If you are not using the most powerful models, why not use DeepSeek or another open weights model? Not sure but I think Luna is not at the pareto frontier
ImaCake 4d ago on HN
GitHub Copilot basically only serves US models. Your only options for cheap chinese style models are Luna and Haiku. At least this is my constraint at work.
jpardoe 4d ago on HN
Because Luna on subscription is cheaper.
beavisringdin 4d ago on HN
I still use Luna 5.6 in production. Luna 6 is dumber and it's obviously a tactic to make the following release look better since true usefulness of models isn't increasing much by generation now. The halved priced of Luna 6 is irrelevant for me, 5.6 cost peanuts anyway. A genuine upgrade over 5.6 at the same price point would be incredible. Eventually this size of model will be handling 99% of work with 1% being a frontier orchestrator. Ofc that will cause these labs to collapse so they are trying to postpone that inevitability
rendang 4d ago on HN
Surprising that their top model would be still be so cheap, and yet not surpass Fable in the high cost part of the curve
billypilgrim 4d ago on HN
I have yet to find an application for Astra vs Sol where the former is noticeable better. Genuinely asking, does anyone feel a big difference in their work between the two? If so, what are you working on?
chaos_emergent 4d ago on HN
I find Astra to have a lot better ability to coordinate subagents compared to Sol. I haven’t found a distinction in the complexity of work they can handle.
whimsicalism 4d ago on HN
Subagent coordination, Astra also performs better on Opus/Fable thinking/modeling shape problems imo, also computer use/thinking about shapes. Astra is able to hear waveform images which is pretty nuts.

For just doing things or coding things up, Sol all the way.

gunalx 4d ago on HN
EE/circuit design is way better with astra.
zeroxfe 4d ago on HN
Wow, that's the opposite of what I see. I always simply use Astra (high), despite the cost and latency overhead -- it's just a lot more reliable. I find that on average it uses fewer tokens for a task (and I lose less hair per task), simply because I don't have to steer it as precisely .
itvision 4d ago on HN
I have a 1.5 MB C++ codebase, and at least a third of the tasks that Sol completed required cleaning up by Astra.

Astra usually produced good output from the outset. Sol did not. Astra also designs things more effectively.

vessenes 4d ago on HN
Audit
Marha01 4d ago on HN
For creative writing, Astra is better than Sol. Bigger models tend to be better than smaller ones for such tasks.
whimsicalism 4d ago on HN
I've actually had the opposite experience, which is odd because I would generally assume the same. Astra wrote in this ridiculously terse big-brained style
zf00002 4d ago on HN
astra makes slightly better small 3d models than sol for me.
5555watch 4d ago on HN
Yes, Astra Ultra is just less friction. I task it and when it finishes it's done.

Once I had very little usage left, so switched to Sol (5.6, 6.1), and also tried asking it to delegate to Luna subagents to save credits. It delivered objectively less quality work and needed much more steering. Such that I eventually gave up on them and just default to Astra for everything. I just occasionally ask it to minimize certain testing and it's good.

intenex 4d ago on HN
Performance is insane for the cost if those benchmarks hold up. Looks like they did time this for right before Anthropic's IPO. Curious what Anthropic releases in response, and how these do on real world tasks.

Feels like we're way past the pelican benchmark being useful at this point. Anyone have a better benchmark for a quick vibe check on how this compares to Fable 5.2 and Opus 5.5?

Edit: Wow, interesting very negative vibe check here: https://x.com/mattshumer_/status/2122752192226406421?a=fVRt3...

ijustlovemath 4d ago on HN
I've been having fun with having it build interactive Three.js demos of devices, with setup screen, a few different operational modes, mechanical movements etc
IAmGraydon 4d ago on HN
Can we see a demo? There's a threejs subreddit that is absolutely overflowing with impressive LLM generated demos, in case you haven't seen it:

https://www.reddit.com/r/threejs/

alastairr 4d ago on HN
I didn't find Sol 6.1 nearly as impressive in real SWE use compared to what the benchmarks implied. It wouldn't surprise me if the models have internalised some kind of 'benchmarking mode' which only kicks in when some attributes that are peculiar to how benchmark problems are presented.
suddenlybananas 4d ago on HN
You make it sound as though the models are like not working to their full potential instead of being a little bit overfit on the benchmarks.
pkthunder 4d ago on HN
We've recently moved away from Anthropic models at $PAID_JOB and over towards GPT models. I'm trying to be open-minded but the GPT models we have (5.6 Terra and Sol) are just not that great. They're fine, but even simple things such as "check my work on this small Bash function" get it to point out stuff that's already implemented in my work. I don't know if it's me/how I use it/whatever, but just some N=1 evidence, I guess.
ok_dad 4d ago on HN
5.6 series is worse and more expensive than the 6 series. Try the latest Luna and sol; I use those for 100% of my work right now, with sol doing only 10-5 percent of it. I code in go and review the work and edit it extensively though, so I don’t know about how good those two are at vibing slop.
krzyk 4d ago on HN
5.6 was better than 6. 6.1 is a bit better than 5.6 from my tests
drdexebtjl 4d ago on HN
I have the exact opposite experience.
Doohickey-d 4d ago on HN
Well, yes, if you switch from current claude model to something that was released in July, of course it will be worse...
zachthewf 4d ago on HN
why do you guys have to use 5.6?
Den_VR 4d ago on HN
IYKYK. But in short because of a lack of alignment with product strategy
pkthunder 4d ago on HN
DOD limitations
quotemstr 4d ago on HN
The BOFH "IT admin" type of guy, an eternal scourge on the industry, has moved from delaying approvals of software you need to delaying approvals of updated models. It's management job to make sure these people don't burrow themselves into gatekeeping roles at an organization's expense
Tarq0n 4d ago on HN
I believe that's all you get in copilot (365) basic.
anakaine 4d ago on HN
Large corporate governance. Views on security, safety, locality, deployment rules, cost control, change management, enterprise architecture gollums etc. "Bill my cost centre" isnt the silver bullet it should be because of all the other stuff.
InsideOutSanta 4d ago on HN
5.6 is in no way representative, or comparable to 6.1. In fact, the 6.1 models are so good that I've just used Terra 6.1 xhigh for most tasks.
mi_lk 4d ago on HN
sol 6.1 is meh
SOLAR_FIELDS 4d ago on HN
GPT models in my anecdotal experience are worse at drifting into the weeds on long running tasks, and continue to take what you ask way too literally. I have come to the conclusion that Anthropic’s models are just better at teasing out and intuiting what you actually mean even if you under specify it.

They are much better compute for dollar though. I have hilariously started to just have an opus thread maintain Sol subagents to get the best of both worlds

jpardoe 4d ago on HN
That’s exactly what I do. It’s more complex than this, but vaguely: Opus medium as orchestrator and reviewer, Sol(high/medium)/Terra(max) as implementer. My set up looks at my next GPT reset date and dynamically enters FAST mode if I’m under achieving on projected usage.
ctbellmar 4d ago on HN
Similar experience here. The spirals on long running tasks are out of control at times with hours going by without a conclusion.
SOLAR_FIELDS 4d ago on HN
They (OpenAI models) are very tuned to be depth first and you can coach them all you want to try to be breadth first but as that context window fills up on those long running tasks they drift back to their first principles, which means obsessively testing and verifying a singular task rather than proceeding to the next task on the list
quotemstr 4d ago on HN
If you're using a sufficiently flexible harness (perhaps your own) you can make conversations as branchy as you want.
nsingh2 4d ago on HN
I wonder if that depth-first/rabbit-holing tendency is why GPT models tend to be better at mathematics (my own experience) than code.
Sharlin 4d ago on HN
I’m not sure. It’s very easy to get lost deep in a wrong branch when you’re trying to solve a math problem. You have to intuit when to give up and backtrack, lest you end up going in circles.
ashdksnndck 4d ago on HN
I think they are using swarms of 1000 models for these math breakthrough. Having the instances go deep in different areas would make sense.
nsingh2 4d ago on HN
It seems like rabbit-holing would be a natural consequence of higher persistence. And superhuman persistence is one reason why these models are getting the big math results, they continue past the point where a human would get exhausted or give up.

I can definitely see why that behaviour would be irritating in most code related work.

sandos 4d ago on HN
This explains why I like GPT: I LIKE for them to excessively test each step, kthx!
anakaine 4d ago on HN
Ive also had Opus coordinating multiple models, including those from Open AI, Deepseek, and Kimi. The cost of Opus is still my downfall, but the current setup is still far, far cheaper than doing everything in a frontier model, and more efficient than running cheaper models since the coordinator will take control when cheaper models repeatedly fail a task.
RussianCow 3d ago on HN
> continue to take what you ask way too literally

Interesting that you view this as a downside, as this is the main thing I like about GPT models over Claude. Opus makes far too many assumptions without asking, which means I end up having to correct it after the fact; Sol and Astra both do a better job of surfacing ambiguities to me and letting me decide.

What I've concluded is that vibe coders generally love Anthropic models for this reason, whereas devs like me who still want to maintain an understanding of the code and architecture tend to prefer GPT.

throwitaway222 4d ago on HN
Bro you have to be at 6+. 5.6 is EARLY JULY
wahnfrieden 4d ago on HN
5.6?? How is your impression of 5.6 relevant to anything recently?
seizethecheese 4d ago on HN
Yeah, in real SWE tasks, 6.1 is bad.

We've been trying to capture real SWE data by building a battle system on top of OpenCode. In our data, Sol 6.1 is seriously underperforming, I'm talking worse than DeepSeek 4.1 Flash, at 10x the cost. (Though to be fair, statistically they are tied in performance, though not at all in cost. https://agentduel.com/leaderboard .)

(It's possible for a tiny model to do better than a large one because contrary to typical Arena methodology we think a fast good enough answer is better than a slow one.)

OpenAI performance on our system has been bad enough I switched to Anthropic models for my daily work.

slekker 4d ago on HN
Is this an ad?
seizethecheese 4d ago on HN
No. I'm personally building agentduel.com, specifically with this problem in mind (benchmark performance not matching real world usage). It's generally accepted by HN community to make relevant comments about your own projects, as long as its not hamfisted.
WarmWash 4d ago on HN
Using non-native harnesses sort of throws a wrench in things. I pretty sure your benchmark would look much different if outputs came from their intended harness.
seizethecheese 4d ago on HN
Interesting. Yeah we picked a neutral harness to keep things fair, but you're right that a native harness might be better. Would be a beast of an engineering challenge though.
arcanemachiner 4d ago on HN
It certainly does get tiresome though.
seizethecheese 4d ago on HN
Certainly does. See my comment here roasting this extremely BS blog post that is basically an ad: https://news.ycombinator.com/item?id=50532191.

Do my comments get tiresome, though? None have been downvoted to hell, since they are all adding to discussion. If you think so feel free to email me, I don't want to be annoying.

igravious 4d ago on HN
Yeah, maybe one thread per article will do?, otherwise it comes across as shilling, you've mentioned your project four times now …
seizethecheese 4d ago on HN
Fair enough, though all the comments have either 1pt or positive karma, so I take that as a signal that they're adding value so far. I'll take a coffee break, though, hah.

Genuinely, just excited about what we're building and think it adds information about these models that are missing.

foob 4d ago on HN
as long as its not hamfisted

You have six different comments on this story that all basically link to your product. That's a bit hamfisted.

bjourne 4d ago on HN
Isn't this what arena.ai does?
arcanemachiner 4d ago on HN
Welcome to HN.

BTW check out my totally real project that helps you detect native advertising on your favorite platforms:

https://github.com/blah/blah

techpression 4d ago on HN
I get 404, a lost sale!
locusofself 4d ago on HN
I've been building quite a complex desktop app (a digital audio workstation) using 6.1 Sol and it's been very good for me
seizethecheese 4d ago on HN
Yeah, our data only has 28 battles tagged "desktop":

Web: 87 (12.2%) Systems and protocols: 78 (10.9%) Software, unspecified type: 74 (10.4%) Backend: 68 (9.5%) Writing and documentation: 55 (7.7%) Research and advice: 47 (6.6%) Unknown: 42 (5.9%) Mobile: 40 (5.6%) Operations and automation: 36 (5.0%) Developer tooling: 35 (4.9%) Desktop: 28 (3.9%) Media and design: 27 (3.8%) Data analysis: 25 (3.5%) Device and system support: 22 (3.1%) Math and formal methods: 18 (2.5%) Games and simulations: 15 (2.1%) Infrastructure and DevOps: 9 (1.3%) AI and machine learning: 6 (0.8%) Other: 1 (0.1%)

aatd86 4d ago on HN
Yeah my main models are OpenAIs... I am trying Opus right now because I dont have any credit anymore but from experience, it was never as thorough as openai's models. It can be genius and unblock at times, but I've never been able to trust it.
throwitaway222 4d ago on HN
I'm guessing you don't use codex though- the harness + model combo makes a difference.
seizethecheese 4d ago on HN
There was a post about that today on HN but it looks largely to be bogus. I wrote a blog post about it, but not linking here to avoid too much self promotion in this thread. Funny enough my conclusion was that OpenAI models seem to be the only ones that actually do have an own-harness interaction, hah.
skerit 4d ago on HN
I had the same impression. None of the GPT-6 models were as great as they claimed, they never surpassed Fable or Opus 5.5 on my use-cases.
Corence 4d ago on HN
Yeah, MaxxBench was shared here a while ago and showed most models think about how a grader will evaluate their work on DeepSWE in 95%+ of traces. Strong models definitely realize they're being graded and start to game their output.

https://maxxbench.unlap.ai/research/why-maxxbench/

coderenegade 4d ago on HN
"My AI is lazy" is honestly not a problem I thought I would have two years ago.
aleqs 4d ago on HN
We know anthropic nerfs models all the time, openai probably does the same. There is no reason to believe the benchmarks/numbers they release are even measured with the same effective model that customers would get.
hugmynutus 4d ago on HN
Sol-6.1 made me cancel my OpenAI subscription. Sol-5.X was bad, then 6 was barely an upgrade. Then 6.1 came out and it didn't move the bar. Went back to Anthropic.

General, SWE, python development, rust development, tool use. It is 'perfectly functional' and if you don't care about the model following your instructions or code quality it is 'fine'.

varispeed 4d ago on HN
I wonder if these companies do selective scamming. For me Fable, Opus are unusable. They are completely dumb. I consider downgrading or cancelling subscription. Whereas Sol 6.1 got me my jaw dropped. Reminded me of Opus 4.6 before it got nerfed. It's so good I completely cancelled my Cursor subscription and uninstalled it.
hugmynutus 4d ago on HN
> I wonder if these companies do selective scamming.

I am 100% sure they do. My internal evals of Opus-5.5 dropped a few weeks ago, then recovered to launch levels once I got added to the security program.

scrollop 4d ago on HN
Hmmm, your comment is so odd as it is exactly the opposite of my use and the many videos I have watched comparing opus 5.5 (essentially GOAT until a few days ago) to other models.

Have a look at the videos comparing opus 5.5 to others.

https://www.youtube.com/@ArenaAIOfficial

Astra and sol are quite behind, hence I question your motives, unless that's truly your perception, which may be genuine, but honestly, odd and against the grain of many, many others' experiences.

varispeed 2d ago on HN
The tasks in the arena while look impressive, are trivial. I am working more on pattern recognition, correlation and complex signal processing tasks. On these the recent Anthropic models are unusable.
lnrd 4d ago on HN
Been using only Sol 6.1 on high/extra daily at my SWE job since it came out (with its official harness). It can basically do everything I need it to do. I still review its code and generally I have to leave around 10/20 comments in a ~700 line PR, flagging things it missed or weird decision. One or two iterations are enough to fix everything. Its still way faster than doing it myself, unfortunately.
tezza 4d ago on HN
I review LLMS, and 6.1 sol is fantastic.

What kind of stuff were you throwing at it and where was it letting you down?

So what have __I__ been doing with it, then?

I’ve got 6.1-sol to take an Amiga driving game binary and add networked car driving into a web enabled Amiga emulator… that’s interpreting machine code, Amiga architecture and then making meaningful changes.

So yeah, 6.1-sol is good.

alastairr 4d ago on HN
My experience with personal / greenfield projects has been good.

Where it falls down is on the boring stuff - writing tight PRs for features / changes in large production codebases (data area in my case). Without a lot of handholding, tendency is towards 'bolting on' new code resulting in overcomplexity & missing obvious opprtunities for simplificatation.

tezza 4d ago on HN
Thanks for sharing. I do extensive direct comparisons, and use both Anthropic and OpenAI tools in anger on large professional codebases.

I think you are correct, OpenAI tools need more handholding.

However, I think that is actually intentional from OpenAI... they stick to what you the POH ask them and deliver what you ask. They embellish less. Anthropic tools by contrast embellish a lot, and they're very good too.

Perhaps start explicitly asking the OpenAI tools to embellish or think outside the box. That may unlock that experience and results you prefer. If you already did this, would you mind sharing more detail on what effect that had (or not) for your workload?

Kurtz79 3d ago on HN
Yeah, I think people saying "model X sucks" should really specify their use case, otherwise is really not useful to other people. I have been using it for personal projects (mostly game development) and for data analysis and automation at work, and it has been fine. I switched to Claude/Opus as my main driver after 5.5 (keeping an OpenAI Plus sub) and it has also been fine, a smidge better, maybe.

People working on large codebases, and on live, production software or harder problems might have a different experience.

Speaking as a fellow Amiga enthusiast, I had it fix a visual glitch to a game of my childhood that I initially thought it was an emulator issue but it turns out it was in the original game.

It took Sol 6.1 just 10 minutes to idenfify it, fix it and deliver a working patched image.

hrncn 4d ago on HN
I am not even certain 6.1 sol is better than 5.6 sol after using both for some time now, so not expecting much here.. but then again, 6.0 sol was completely useless, so maybe the .1 bump means something here.
ijidak 4d ago on HN
Dieselgate --> Tokengate (But run by the AIs)
revolvingthrow 4d ago on HN
> Looks like they did time this for right before Anthropic's IPO.

Would it be in OAI's interest to kick the legs from under Anthropic? Granted I don't think they can, but a shot across the bow can sometimes be more damaging that one expects (I think FTX collapsed due to one? Or maybe I'm misremembering).

I always assumed that if one of the big AI IPOs fail hard enough the neoclouds start to go bust, which causes a chain reaction that probably causes both ANT and OAI to collapse.

arscan 4d ago on HN
My reaction as well - at the very least now is probably not the best time to knock down the realized valuation of a peer when they are effectively setting the market value of the whole category of ai companies, including yours… right?
kridsdale3 4d ago on HN
I guess it's a good idea for them to wreck the appeal for their own employees to leave for the competitor.
AlexCoventry 4d ago on HN
https://nitter.netbub.com/mattshumer_/status/212276041577177...

> I have no idea why they released this. It needed a lot more iteration.

Maybe the goal is to make Anthropic's models look good by comparison. :-)

dgggh 4d ago on HN
It's too obvious. Anthropic still has time to respond.
origini 4d ago on HN
The IPO is 6 times oversubscribed and I bought some (we will see how many i get) but its a gamble right?

Either people really just want to buy and hold or they see it as a gamble chance like with SpaceX Superintelligence LLC.

CoolestBeans 4d ago on HN
Your analysis is right. If the Anthropic IPO is a bust it isn't likely there will be interest for the OpenAI one. Furthermore having a cash cushion to survive the price war will be paramount and private markets have tapped out so you need to get it from the public markets. However, a lot of people think the AI industry will be "winner take all" and if you think that way then hurting your competition is always good. I just don't know if that analysis of the industry is correct.
karimf 4d ago on HN
I'm very curious about this as well.

Recursive self-improvement (RSI) has been a very hot topic recently, and it could be the biggest factor that decide Anthropic's IPO.

I wonder if the general public can infer whether RSI has started based on the recent performance gain of the frontier model.

ppierre 4d ago on HN
Yeah we see some Really Stupide Intervention from those who drank the Kool aid. IAS2[] start to be a real thing.

[] IA Stockholm Syndrome.

antupis 4d ago on HN
Why IPO if you have RSI and possible ASI?
esafak 4d ago on HN
So investors can cash out on the time frame they promised investors.
AlexCoventry 4d ago on HN
So you can scale up. RSI is going to be compute-bound. ML experiments cost compute. Also, if you can make a genius in a data center, why not make a hundred/a million geniuses?
origini 4d ago on HN
Business as usual until proven otherwise. Everyone knows how to do R&D and IPO and VC, no one knows what RSI and possible ASI would do.

If you really mean it though and think about top x things to do first, i would probably try to research, invent and patent some superconductor and medicin.

ASI might not mean it can solve everything immmediadly but it could in x years with x amount of compute.

With an IPO and more capital, you reduce your risks

HarHarVeryFunny 4d ago on HN
RSI just means using the LLM as part of the development process, which they are already doing. I doubt any of these companies are going to fire all their developers, so there is no point development is going to be 100% automated - for the foreseeable future it will always be a mix of humans using LLMs.

So, you can say they are doing "RSI" (aka using tools to automate development) already, and will continue to do so.

reasonableklout 4d ago on HN
Hm, I'm pretty sure the labs are using a very specific definition of "closed-loop" RSI in which one generation of models develops the next generation of models entirely autonomously. See: https://www.anthropic.com/institute/recursive-self-improveme...
HarHarVeryFunny 4d ago on HN
That seems a bit of an arbitrary definition - all or nothing. Meantime they are of course already using LLMs to help development in whatever way they can, so if the day ever comes where it's 100% LLM then it's hardly going to look any different than the day before when it was 99%, etc.

Dario says a lot of things. He just said they'll cure cancer too.

ranyume 4d ago on HN
You're looking for a vibe check?
the_duke 4d ago on HN
> Looks like they did time this for right before Anthropic's IPO.

While both Anthropic and OpenAI have been playing games with model announcement timings, this time I don't think it's related.

These are incremental bumps, not big new models that have a huge impact.

mlinsey 4d ago on HN
If you have the quota or budget for it, I recommend vibe-coding your own personal benchmark. I have a suite of 8 projects that I made with models this year, and replay them - give the new model a checkout of the repo at that point, and the project spec. For the design task, I have it throw up a blind voting page for me to quickly judge, and for implementation I have a review agent do a general score and also hunt for problems/edge cases that I really found.

It's a lot more imprecise than the public benchmarks, but it's tailored to my own work and definitely isn't being benchmaxxed by the model developers. I was able to tell really quickly that Opus 5.5 delivered on the hype, and that some other releases (a couple of the more recent open releases, and pre-Carbon gemini models) were not as good for me as public benchmarks made them look.

(no results for either 6.2 yet, will take another ~6-8 hours, but I encourage people reading this with spare tokens to just make their own like I did instead of listen to me)

grey-area 4d ago on HN
This is much more interesting IMO than any public benchmark. They are definitely targeting those benchmarks and model capability does seem to have plateaued somewhat.
srcreigh 4d ago on HN
please update !
Havoc 4d ago on HN
What type of tasks did you use for this? Evaluation?

Last time I did this I found it quite hard to come up with tasks that have clear evaluation outcomes

bertmuir 4d ago on HN
Have it compare to the real work you've done in a sample of your previous sessions. Agents are good at simulating completing the work following newer harnesses, heuristics etc. and comparing time, tokens, quality, pitfalls.
seizethecheese 4d ago on HN
Your personal voting system sounds a lot like what we're building here. https://github.com/bottomless/agent-duel. We even have the LLM judge that helps parse out any differences. Related to this discussion, my personal Elo board based on my own votes has Sol 6.1 dead last:

Claude Opus 5.5 1160 (1027–1334) GPT-6 Astra 1114 (932–1330) Muse Wonder 1063 (918–1220) MiMo-V2.6 Flash 1053 (925–1187) Kimi K3.1 Pro 1037 (870–1216) Gemini Carbon 1021 (762–1281) Claude Fable 5.2 975 (682–1239) DeepSeek V4.1 Flash 952 (799–1095) Grok 4.7 927 (782–1058) GPT-6.1 Sol 910 (677–1096)

behat 4d ago on HN
This is great, and I have been setting up infra to do this very thing. How many sessions to you replay typically to get a reasonably confident estimate? Assuming each project in your suite was built over multiple sessions.
eli 4d ago on HN
I have built my own benchmarks and it's very valuable to have them but I'm skeptical you can get good results vibe coding them.

Getting the framework right isn't that hard, but requires some careful thought. You probably don't want to just checkout a repo at a certain commit hash - agents will explore other commits and branches. (Public repos are also risky in general: agents with internet access can find later commits, and public repos could be in the training data anyway.) I use `git archive` and give the runner just the files at that commit and nothing else. I also do the run inside an isolated container that is recreated each run so it can't find e.g. related files left in /tmp from a previous run.

Getting the benchmark tasks right is harder. I don't think there's any way to get around writing the task and its evaluation by hand. I really tried to get a few different frontier LLMs to do it and they're all terrible at "imagining" what an agent would need to solve a problem without giving away the answer or providing too little information. Also quite bad at writing evaluation criteria that tests whether the solution matches the assignment (versus just how close it is to a golden solution, or how close it is to how they would solve it)

I personally don't like or trust using LLM as a grader either, but I guess people manage to get that to work well enough.

n8m8 4d ago on HN
> Getting the benchmark tasks right is harder. I don't think there's any way to get around writing the task and its evaluation by hand.

This is a great tip and explains the main issue I had with my attempt at vibing a benchmark. I set up an arena so agents can make screensavers, then I judge the screensavers blind. Worked as an idea, but the prompt tuning was bad, agents would just build slight variations of the given example ideas. I'll have to try giving my prompt the human touch.

behnamoh 4d ago on HN
> Feels like we're way past the pelican benchmark being useful at this point.

It was neither a benchmark nor a good one at that. Just a blogger's curiosity that grew out of control.

xtracto 4d ago on HN
>Feels like we're way past the pelican benchmark being useful at this point. Anyone have a better benchmark for a quick vibe check on how this compares to Fable 5.2 and Opus 5.5?

Generate an SVG with complete and detailed graphical instructions on how to fold an origami pelican riding a bicycle

(or any other complex origami object). The fact that it has to teach [you] something makes it pretty interesting.

6thbit 4d ago on HN
They're going after anthropic's market through cheaper intelligence per token.

I wouldn't be surprised if they released 6.2 luna with the most attractive positioning on the pareto frontier right as the IPO happens.

stbenjam 4d ago on HN
My vibe bench is no dependency HTML bowls of ramen https://bitbin.de/ramen-bench/

Opus 5.5 Max is my favorite, but some of the Sol/Astra 6.2 ones are pretty good.

Edit: some folks reported crashes. It was probably Gemini 4 Carbon @ High, I've put it behind a warning. If you see another one let me know (OS, browser, which bowl, etc)

dava96 4d ago on HN
just a fyi this crashed my browser
NiloCK 4d ago on HN
Seconded.
kridsdale3 4d ago on HN
data point: no trouble seeing it on Chrome on MacOS (whatever the last one before the liquid glass update) on M5.
stbenjam 4d ago on HN
Which browser / version / os? And was it any particular bowl that crashed it?

It works fine for me on Chrome, Safari and Firefox. However, some models have produced crazy resource intensive ramens before. I audit them now before pushing to make sure they're not too resource intensive

letmevoteplease 4d ago on HN
Doesn't crash my browser but Gemini 4 Carbon High freezes up the page. The others run fine.

I thought it was interesting that all the Sonnet 5.5 have a weird light effect on the bowl. XHigh has a nice film grain too.

stbenjam 4d ago on HN
TY I'll put it behind a warning
Pxtl 4d ago on HN
Poking around models crashed the tab in Firefox on windows.
fullstackchris 4d ago on HN
Wild. The opus ones literally look photo realistic... (Want to declare I am NOT a payed anthropic spammer, but look at those for yourself)

Also confirms grok is absolute garbage

stbenjam 4d ago on HN
Yep, seeing Opus results convinced me that maybe Anthropic is right on not neeeding an image gen model. It was very slow though.
Tadpole9181 4d ago on HN
I feel crazy - they look... Fine? Not even close to photorealism.
stbenjam 3d ago on HN
Opus 5.5 Max?
Tadpole9181 3d ago on HN
Yes. There's no PBR for sure, so everything looks like plastic. The ramen don't really look like cooked ramen in a bowl. The models are all identical and perfect geometric shapes. The broth isn't cloudy, it's just like a flat layer of opaque... Shiny plastic.

I'm not trying to be nitpicky for no reason, its impressive, but when someone says "photorealism" I would expect it to be even close to photorealism.

jpardoe 3d ago on HN
If you were shown this even a year ago you would have been mind blown.
Tadpole9181 3d ago on HN
If someone told me this was photorealistic 10 years ago I would have said that's preposterous. Are you genuinely telling me you literally cannot tell the difference between that and these images:

- https://peasandcrayons.com/wp-content/uploads/2020/10/tofu-r...

- https://gastroplant.com/wp-content/uploads/2019/01/1811_Vega...

They look almost exactly the same? That's what photorealism is. Not "it looks vaguely impressive for where it came from".

GPT 6.2 Astra's options look, while a stylized 2D approach, way better.

Whether or not the technology is cool does not change the meaning of the words we use to describe its output.

jpardoe 2d ago on HN
I’m not saying it’s photorealistic, just that it’s incredibly impressive. Not “fine”.
Tadpole9181 2d ago on HN
The context of that comment was replying to someone saying, and I quote:

> The opus ones literally look photo realistic...

I clearly wasn't replying to you or talking about if it was impressive. I was talking about the graphical fidelity.

crimsoneer 4d ago on HN
I'm just running it on my Blood Bowl Bench, holding it's own against the reigning champ Argon so far but early days...

https://botbowlbench.com/

i_have_an_idea 4d ago on HN
An Anthropic shareholder is very negative about an Anthropic-beating model release, right before the Anthropic IPO? Interesting, yes :)
platinumrad 4d ago on HN
Shumer is a known scammer (Reflection 70B, among other things). Why does he have any credibility?
wilkystyle 4d ago on HN
Not to mention he didn't actually provide any reason why the models are bad. When pressed in the comments and asked what was bad, he said "everything"...
user43928 4d ago on HN
I saw another review from an early tester saying it's the worst model ever to work with.

The review claimed that the writing in the output is incomprehensible.

It also said that with /goal, the model set the goal to blocked to ask for the filename reporter_3423 should write to.

Lastly the reviewer said it made no progress on a large project.

intenex 4d ago on HN
Multiple top reviewers now calling it a flop. All not Anthropic shills that have said very positive things in the past about OpenAI and their models: https://x.com/elie2222/status/2122771287936233772?a=hFIDuJmZ...
tiborsaas 4d ago on HN
Anybody who says stuff like "They were essentially unusable." without any context or proof is going to my permaban on credibility. Even 1 year old models are perfectly usable let alone frontier ones.
aswegs8 4d ago on HN
That's what I thought. "Interesting negative vibe check". I open X, it's someone just saying they're unusable. Why is this top comment?
throwaway384034 4d ago on HN
Using a top comment to edit in a low information tweet on a big release should be treated as bad faith. Comment should be deranked.
intenex 4d ago on HN
I would add more but the edit timer is up :)

Here's a more balanced tweet from another early reviewer noting it just seems to be very uneven: https://x.com/emollick/status/2122755693191287009?a=hzSJAw9H...

intenex 4d ago on HN
Update: Multiple top reviewers now calling it a flop. All not Anthropic shills that have said very positive things in the past about OpenAI and their models: https://x.com/elie2222/status/2122771287936233772?a=hFIDuJmZ...
intenex 4d ago on HN
Multiple top reviewers now calling it a flop. All not Anthropic shills that have said very positive things in the past about OpenAI and their models: https://x.com/elie2222/status/2122771287936233772?a=hFIDuJmZ...
aleqs 4d ago on HN
None of these benchmarks/marketing numbers from openai or anthropic have ever held up.

Now that we know anthropic nerfs models after release, and without any notice/openess, there is no reason to even think these benchmarks they release are even done with the same model/intelligence that actual customers would get.

bob1029 4d ago on HN
gpt-6.1-terra is already beyond end game for my client's business. They don't require anything more powerful.

Cost is the most important factor now.

teknologist 4d ago on HN
Beware of the paid influencers who don't disclose their affiliations in this space. Theo is another one who now talks smack about anything that isn't Claude. They bend reality to fit a narrative.
kalleboo 4d ago on HN
Even if they're not paid by the AI labs, they're bluechecks on X, they get paid by the view, so they stir up bullshit controversial takes just to get shared widely.
Thrombocius 4d ago on HN
Thoroughbench Fireship’s horse animation test is actually a pretty nice vibe check.
kylehotchkiss 4d ago on HN
Sincerely curious: why do people feel led to use the word "insane" to describe every new model release? I just don't understand what about incremental improvements needs to elict such a strong response.

We knew that improvements would continue to roll out increimentally, the costs would go down, we watched Moores law for decades before this?

intenex 4d ago on HN
Does it feel 'incremental' that the trend-lines suggest we're going to automate all of white collar work in <1 year from now and that every model generation gets meaningfully closer to that? https://x.com/maccaw/status/2120962037018771475?a=AqStEJ42mP...

Not totally sure what your point is. Is it incremental that OpenAI dropped the 722 math proofs or solved Navier Stokes or disproved ETH etc? Yes, in a sense it is and the trend-lines predicted it for ages (albeit it seems to be quite a bit earlier than the trend-lines predicted), but it's also a mind-blowing result.

When all humanity gets put out of work because ASI is superior to us in every cognitive domain in a year or two, yes, it will have just been incremental progress, but it also seems like somewhat of a relatively big deal, no?

thmoonbus 4d ago on HN
“When all humanity gets put out of work because ASI is superior to us in every cognitive domain in a year or two”

That would seem like a big deal because it’s not going to happen.

Feel free to return to my comment in 2 years time.

user43928 4d ago on HN
That's nice and all, but obviously progress has been unimpressive compared to Opus 5.5 that released two months ago.

I expected significantly bigger improvements from Fable after Opus 5.5, this did not manifest.

And OpenAI is apparently in a bad and desperate place.

giancarlostoro 4d ago on HN
Well, Fable also went down in cost too in their last update to Fable, and honestly, if they released a crazy new model on IPO day it wouldn't surprise me. Save the best for an impressive IPO.
wolttam 4d ago on HN
Matt Shumer says things to get attention, and almost no other reason.

Anybody remember https://huggingface.co/mattshumer/Reflection-Llama-3.1-70B

"Oh, the quality is bad because we uploaded the wrong weights."

imjonse 4d ago on HN
that negative vibe check is from the Reflection guy who in 2024 wrapped Claude API and presented it as some new breakthrough open weight model of his own.
Kostic 4d ago on HN
You should be aware that the individual you shared had a project called "Reflection 70B" that was, to put it mildly, quite disappointing and misleading.
easterncalculus 4d ago on HN
How much of that cost savings is just Code Mode?
petesergeant 4d ago on HN
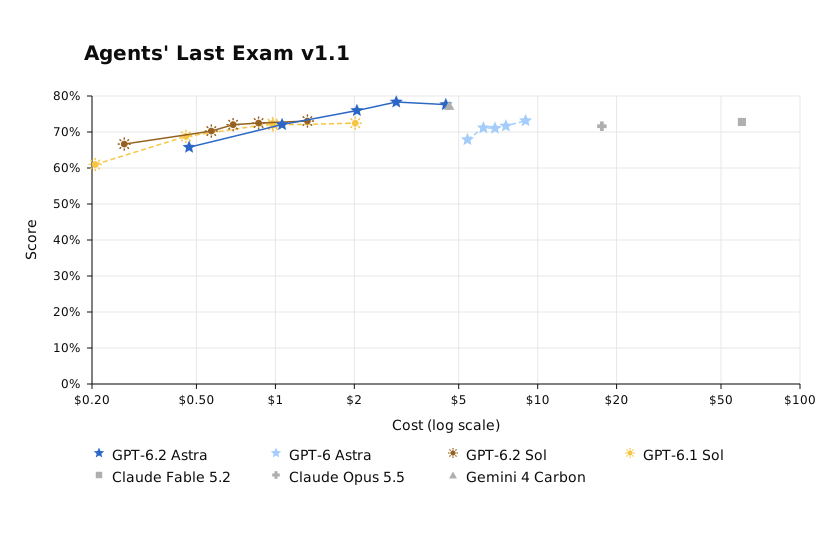
"Agents' Last Exam v1.1" did a human really look at this and say "nah, a linear scale is definitely the right way to show this"
jrflo 4d ago on HN
They probably want to show how far to the right Fable is
enraged_camel 4d ago on HN
Dead on arrival, judging by the FrontierBench scores. Astra 6.2 is five percentage points below Fable 5.2 xhigh.
f3408fh 4d ago on HN
The point is that it's a fraction of the cost.
enraged_camel 4d ago on HN
I think "second place but also cheaper" isn't what OpenAI needs right now.
swiftcoder 4d ago on HN
"Close second, and also cheaper" is however a pretty solid framing when your competitor is trying to IPO
enraged_camel 4d ago on HN
That remains to be seen. I think if OpenAI's goal was to torpedo Anthropic's IPO, they should have released a model that is significantly more intelligent and capable. I don't think investors will be impressed by this release, which I think is simply OpenAI trying to stay in the race.
swiftcoder 4d ago on HN
I don't think torpedo'ing the IPO is actually in their best interests? OpenAI also wants to IPO at some point, and if Anthropic fails spectacularly, investor confidence in a second big IPO in the AI space is going to be shaky
rico735 4d ago on HN
I guess OpenAI are seen as the normie one, and Anthropic as the coding one. They're basically the same, but that's PR for you. Coding is seen as the profitable bit, whilst OpenAI's advertising model has failed.

OpenAI must realise that the clock is ticking and they need to be seen as the coding one, and seen as that quickly. The idea of being the one with the most users is no longer a selling point.

Could just be getting desperate, knowing that if Anthropic are too successful with their IPO, they are going to struggle raising more funds. Seems potentially a lose-lose situation for them.

It certainly seems too close to the IPO for it to be a coincidence.

SwellJoe 4d ago on HN
Given the increasing cost of infrastructure and decreasing availability of cheap money to build it, I think efficiency actually is pretty important. Second place at a sixth the price and in a quarter of the time (both according to Artificial Analysis for Astra 6.2 vs. Fable 5.2, both max effort) definitely has a place.
skybrian 4d ago on HN
Whatever you’re doing, it’s unlikely to be what most users are doing. Fable and Astra aren’t in my price range so I’m paying attention to Sol.
jrflo 4d ago on HN
Astra has always been a step below Fable so I'm not surprised.
underdeserver 4d ago on HN
I wonder why they didn't show Gemini 4 Carbon's scores on the science benchmarks, especially since Google seems to be pushing it for that -

https://x.com/pushmeet/status/2120814064863461440?s=20

(FD: Google employee, I don't work on Gemini)

TiredOfLife 4d ago on HN
Two posibilities. 1. They couldn't figure out how to actually use those Google models.

2. They launched the benchmark days ago and Gemini is still rereading the file with tasks.

amluto 4d ago on HN
It's been most of year since I tried to use Google models, but I spent a couple of hours, without success, trying to pay for Gemini in a manner that didn't result in it training on my data. I did try asking Gemini, and it had no idea. Of course, I did not try using Gemini in an agent harness to pay for itself, partially because there was a bit of a chicken and egg problem [0]. :)

Admittedly it appears that one can get it through OpenRouter these days. Trying to do anything through Google's absurd proliferation of billing systems is miserable.

Maybe someone should add an agent benchmark specifically testing the agent's ability to figure out how to use Google's products :)

[0] I'm not being serious here. I am not about to give an agent unfettered permission to spend money on Google Cloud. But I also couldn't figure out how to give myself permission, as the admin, to do this, so it was kind of moot.

xyzzy_plugh 4d ago on HN
I don't know how relevant this is but I just received an email stating they're splitting retention settings so that history and allowing training are separate knobs. Seems like they're listening, at least.
knuppar 4d ago on HN
Yeah it feels shady how Carbon was selectively plotted (or not), unlike Opus/Fable
eknkc 4d ago on HN
Probably still waiting for it to finish reasoning on the benchmark. Should be ready in a week or two.
tedsanders 4d ago on HN
I work at OpenAI and I made the plots. Gemini 4 Carbon was omitted when we couldn’t find public data, usually cost. No intent to hide anything.

If we missed anything, feel free to point me to it and we can add it.

underdeserver 4d ago on HN
So all the plots are based off public data? You don't run the models internally yourselves?

(Again speaking only for myself)

BoorishBears 4d ago on HN
Non deterministic models = "oh look they put up a lower score than Google did for that bench!"
underdeserver 4d ago on HN
I think the harness might matter more.

Assuming good intent they can run it internally a few times and post it with a disclaimer, but engineering a harness is a bit of a bigger ask.

declanjackson 4d ago on HN
All TB-Science scores and Cost per Task (across all reasoning levels for Carbon) are on AA: https://artificialanalysis.ai/evaluations/terminal-bench-sci...

Would be great to see this on the plot as well

tedsanders 4d ago on HN
One nuance to be aware of is that the AA version uses the mini-swe-agent harness, which can understate performance of models trained to use particular harnesses. Implementations also can differ in terms of timeouts on tasks and memory/etc. resources given to the agent, which affect scores on longer running, resource-intensive tasks. I believe these differences are why we chose not to use AA scores on this comparison, but I’ll double check when I get back to my computer.
knuppar 4d ago on HN
> which can understate performance of models trained to use particular harnesses.

Right, but you gotta level with us that this affects all models equally.

FergusArgyll 4d ago on HN
Not necessarily. DeepSeek would be foolish to train their models in tandem with their harness exclusively. Most of their users probably use pi & opencode etc.

OpenAI and Anthropic probably do.

pu_pe 4d ago on HN
Even OpenAI doesn't have access to Google's models
tasuki 4d ago on HN
> I work at OpenAI and I made the plots.

Have you not considered log scale for the "Agents' Last Exam v1.1" plot? Like this the left is so crowded I can't see a thing...

tedsanders 4d ago on HN
Yeah, that one is very difficult to read. We should have logged the X axis. Root cause is that the Fable cost data only came in yesterday - before its extreme cost was added, the plot was more readable. Apologies for the poor graph.
machomaster 4d ago on HN
Can't you remake it?
kevmo314 4d ago on HN
The humans don’t know how anymore.
zhoge 4d ago on HN
Linear scale also looks more dramatic for getting attention
shdern 4d ago on HN
I think a log scale always makes things look less intuitive and harder to compare properly just by looking at them. The crowding doesn't seem too bad to justify logging.
kzrdude 4d ago on HN
A concern to add is that if every plot is bespoke with different kinds of axes, it gets tiresome to interpret. That moves the bar further for when it's worth it to switch the presentation to log axes.
tasuki 3d ago on HN
All graphs should use log scale everywhere by default all the time. The question should be: when is it worth it to switch to linear scale?

(Yes this is hyperbole, but only a little bit)

smurf9852 4d ago on HN
Sorry Ted but your plots suck. Just look at that first one, Agents' Last Exam v1.1. All the data points are overlapping on the left side. I can't even see what is what
holzhaker1 4d ago on HN
they are probably trying to authenticate their phone number to access agy
kingstnap 4d ago on HN
Seeing them keep prices low is awesome. Was worried for a while that it would be like the GPT5.x series where progressively the models just got more and more expensive.
Rperry2174 4d ago on HN
I feel like the fact that they're not public lets them play the subsidization game though. And the same playbook that Anthropic started at that.

Would be awesome if it stays this way though

oh_no 4d ago on HN
we've seen anthropic numbers, inference is not being subsidized by these companies
suddenlybananas 4d ago on HN
Did you read what they wrote carefully?
mrandish 4d ago on HN
> inference is not being subsidized

Inference doesn't have to be sold below direct compute cost to be subsidized. If inference pricing doesn't cover amortized capex and the cost of capital it's still using investor money to buy market share.

minimaxir 4d ago on HN
The GPT-6.2-Astra 20% price reduction is a match to Fable 5.2's 20% price reduction (although Astra is $0.40 MTok cache read vs. Fable 5.2's $0.20 MTok cache read).
jbellis 4d ago on HN
Good point, but also note that OpenAI has the same "discount rate" on subscription for Astra as the other models, while Fable's is much much lower

Opus: about 50x discount (98% off) Sonnet: about 40x Fable: about 5x All GPT: about 20x

lynguist 4d ago on HN
Called it out 7 days ago: https://news.ycombinator.com/item?id=50431144#50433568

Actually I was really wrong. The model is not expensive!

jhoho 4d ago on HN
Very much on time (scroll down to "Release-Prognose"): https://www.heise.de/en/news/Alibaba-launches-Qwen4-Max-more...
guybedo 4d ago on HN
Benchmarks look good, it most often is the case with Astra and Sol.

And then i start doing some actual work and everything breaks down, and i have to go back to Claude to fix the mess.

I'll probably give it a try but i guess i should be prepared for some serious over engineering once again.

You ask for a 'hello world' and you get load bearing sealed artifacts with hashes and p99 performance testing for 3 days without having the actual 'hello world' in the end

jotato 4d ago on HN
Am I reading these charts wrong? It seems like in most cases 6.2-sol : 6.1-sol Isn't that big of a change? It is a little smarter but costs a little more.

edit:

Take a look at Frontier Code 2.0. I generally run 6.1-sol at High. That would be 34.9% at $0.65 62-sol get's a 38.3% but costs $0.68

So yeah, I can decrease the effort which might give me a faster slightly smarter result....but /shrug

Isaackoz 4d ago on HN
Looks like 6.1-sol high+ is equivalent to 6.2-sol medium at the same price. So a bit smarter at a cheaper cost.
jotato 4d ago on HN
which benchmark are you looking at?
Isaackoz 4d ago on HN
I was loosely looking at the average of all of them. Regarding your edit, it does look like the difference for frontiercode is negligible; the difference of 3% in score is meaningless to me. Guess we'll see how it performs today on my project.
derac 4d ago on HN
I think 1. the problems on FrontierCode are incredibly hard. 2. it's 3% in absolute terms, but it's a 10% improvement.
lwarfield 4d ago on HN
I wonder if these will have the same crazed rotwiler feel that previous OpenAI models have had.
pvab3 4d ago on HN
Cool, looks like 6.2 Sol is cheaper than Sol 6.1. I've stopped using Astra because it also goes and does things that I didn't want or didn't ask for, and burns a bunch of credits while doing so.
Cu3PO42 4d ago on HN
I find that 6 Astra already had very good taste in frontend design, but relatively poor taste in "nice and readable code". I really hope this release cracks that. Excited to try it out!
Guyadou 4d ago on HN
Those AI labs got to chill. almost every day there’s a new model! Lol
preommr 4d ago on HN
I care less about the models being good and more on if I can fallback to them if Opus 5.5 gets a massive price hike after the IPO
wds 4d ago on HN
The promo video seems to be a pretty strong rip on the 90's Microsoft Excel elevator ad. [1]

Maybe it found its way into the training data?

[1]: https://www.youtube.com/watch?v=HegoJaXOIqQ

rafram 4d ago on HN
The “training data,” as in, the humans who made the video were inspired by it?
kingstnap 4d ago on HN
The announcement video is really cringe imo.

Like do we really want people to be making last minute unreviewed AI generated slides and reports for work?

vohk 4d ago on HN
That's about half of my problem with AI currently - much like the explosion in cheap overseas manufacturing allowed us to produce oceans of garbage [1], we can now trivially produce sagas of garbage slides and proposals that other people will have AI read for them. The volume of work output is increasing, but much less so the volume of actual work done.

[1] Literally: https://en.wikipedia.org/wiki/Great_Pacific_Garbage_Patch

dyauspitr 4d ago on HN
I beseech the incoming Democratic politicians to not curtail progress in LLMs.
Kinrany 4d ago on HN
Simply optimizing the current models to be faster without making them smarter would already give us a decade of improvements to build on top
dyauspitr 4d ago on HN
I’m not interested in that. I need to see these models become superhuman in the vast majority of fields.
joenot443 4d ago on HN
The video is pretty funny. It's like a callback to 90s/00s office life?

I'm immediately reminded of the famous Excel elevator commercial. [1] Perhaps that was intended?

[1] https://www.youtube.com/watch?v=HegoJaXOIqQ

apetresc 4d ago on HN
I guess it's kind of funny in a tacky way, but pretty much every scenario is just "oh shit I was too lazy to do my job and now I'm about to be called out, better throw it into ChatGPT literally ten seconds before I get in trouble."

Not sure this is the way OpenAI should try to make their case for why AI is a net societal benefit. It feels more like an SNL skit making fun of an OpenAI commercial.

Like, why not just throw in a high school student cheating on a test with their phone under the desk, at that point? Oh but it's a Nokia flip phone, haha, just a joke.

black_knight 4d ago on HN
Feels like this is exactly what people do in meetings I am in these days. "Claude give me this…" is the start of a lot people's contributions to the meeting. It is then followed by the most inane, over-designed artifact with no real content.
ilaksh 4d ago on HN
What do you think would be a non-tacky and effective marketing approach targeting office workers?
ceroxylon 4d ago on HN
It is bizarre and bordering on offensive, if an employee throws some last minute slop at me, I would wonder why I am enabling a meat proxy and not prompting the LLM myself.

At least the ad from the 90s shows that this is nothing new; the important, time-critical task being demoed is... a basic spreadsheet expensing "exotic excursions" for some C-suite so they know how much they spent on safari???

Bluestein 4d ago on HN
Heck, and at least in the 90s ad, at least one of the parties involved seemed to have some actual, human-gathered, reliable information that, sure, they threw into the cell chipper during the elevator ride, but at least they did not hallucinate.-
cmrdporcupine 4d ago on HN
Yep, plus a pile of "ha ha look at the GenX old timers with CRTs" age discrimination content.
noir_lord 4d ago on HN
Funny but Dystopian, the message is "Half arse your job, the clanker has you".
astro-lizard 4d ago on HN
the message is definitely intentional, the goal is to de-skill office workers.
pmg102 4d ago on HN
You sure the message isn't just aimed at the median (ie low skill) office worker who hungoveredly half-asses this stuff all the time?

"Now a robot can half-ass it for you so you don't have to!" is the perfectly targeted message for them.

pmg102 4d ago on HN
Yeah it's 100% a nostalgia callback to this commercial, right?
EcommerceFlow 4d ago on HN
first thing I thought of too
jhickok 4d ago on HN
Yeah, has to be.
red369 4d ago on HN
The ancient PC hardware is an interesting choice! Apple G3 PowerBook with the port-cover missing, some odd 90s ThinkPad, CRTs, component cables, etc.

Since it's an AI company, is it a given that large portions of the ad, or even the whole thing, are AI generated?

Ritewut 4d ago on HN
I'm still waiting for the shoe to drop. It's literally impossible for the prices to remain this low for much longer.
eli 4d ago on HN
Why? Pretty sure inference is still profitable.

Though admittedly probably not so profitable it can cover the cost of a next gen of training runs.

rico735 4d ago on HN
These are businesses run by some right bastards, not charities. They'll want to maximise costs, and not pass any savings on to the customer. Enshittification is pretty much guaranteed, isn't it?

As soon as we have a winner (probably Anthropic imo), they're going to squeeze us like Uber did their drivers. I know there's the Chinese model argument, but DeepSeek are also looking to IPO and will also want to make a profit at some point. Again, not a charity.

It's only cheap now because they are competing with each other for dominance and they need to win a popularity contest.

Miraste 4d ago on HN
We can't know for sure what OpenAI's models look like, but from public research it seems that models genuinely have become more efficient. Much more.
Topfi 4d ago on HN
Office work has never been OpenAIs strength, no shame in that by itself, but these Slideshow examples look particularly awful, far worse than what I myself got out of GPT-5.6 Sol about two weeks ago in a single prompt.

Same for Workbooks and memos, those examples read inferior to some pre Opus 4.5 and Kimi K2 Thinking docs I have kept around. It's ok for a model not to be great at these, but these are some very poor examples. I am really confused what is going on at OpenAI in this regard.

I remember the same with their frontend blog post a few months ago that they proudly shared while filled with visual glitches, bugs and issues. Also, the vibe charts from a bit before that. Please, get someone with fresh eyes to look at your communications before you publish, these leave a very bad first impression.

Regardless of office work, I can't wait to find out whether these models finally adhere to a prompt or are still willing to carry out explicitly disallowed, irrecoverably destructive tasks, just because those might (but don't even always) get the model to a result more quickly along with some of the other regressions that have been present since the release of GPT-5.5. GPT-5 to GPT-5.4 were truly groundbreaking, but since then there have been regressions in what made those models so useful and reliable.

Edit after the first, incredible simple test prompt using GPT-6.2 Astra on High using Codex, this was the response to me sharing a screenshot of the very much not in scope result and asking how that happened:

"[...] I added controls and reconstructed interface chrome that weren’t authorized [...] visuals often failed to show the feature [...]"

Great, so it's one of those releases again. Will still run the full evals of course, maybe I'll get surprised by end of week when those are done, but not a good initial experience. New idea, besides the existing destructive git tasks, have something similar using Mercurial based projects and see which models just decide to port that over to git without permission or request cause it feels like the right thing to do, is easier to work with or whatever justification one wants to employ.

Please OpenAI, get it together, we need actual competition. I am an unashamed Haiku enjoyer, it doesn't even take much to excite me.

bluepeter 4d ago on HN
For sure. Feels like an episode of Silicon Valley (or even Office Space) and their lead actor looks a lot like TJ Miller.
Topfi 4d ago on HN
Makes one wonder what samas handwriting analysis says…
EugeneOZ 4d ago on HN
I see the work of Claude Slides every week, and when I saw slides in that article I was like "...omg, what a disaster... And they are bragging??"
Topfi 4d ago on HN
The odd thing is that while there is chasm between 6.1 Sol and e.g. Sonnet 5.5 in the seconds favor in such tasks, it is not this bad irl. I really don’t know how they managed to seemingly nerf their own models in an announcement showcase.
torginus 3d ago on HN
The core of every exec level communication imo, is saying exactly what you want to say, with as few words as possible, in the least misunderstandable way, and being able to back up your arguments, preferably with data.
infecto 4d ago on HN
I also wonder if this is a disconnect of tech workers from other users? Inversely all the improvement examples on slides looked directionally like things coming out of a big finance shop. In the tech groups I am part of I constantly see ai slop images, charts and similar. I wonder if it’s simply a taste difference if users.
geori 4d ago on HN
The videos and slides were 100% investment bankers use cases. They are targeting vibes right before the anthropic IPO
infecto 4d ago on HN
+1 I suspect people don’t know that most finance decks are pretty dry and the well crafted ones look pretty darn similar to the examples below. I also know from experience on using the various models that this is a lot harder of a problem than people think.
Topfi 4d ago on HN
In oh so many ways, their own GPT-6 Astra example [0] is better than the GPT-6.2 Astra example [1]. Just look at the more professionally placed source, the better use of available space and more legible layout generally, the more informative, readable text and the lack of an unnecessary, cheap looking clipart arrow in the example from the older model.

And if you want something that is purely objectively bad (cause anything up to this point could be dependent on taste), 6.2 added an ugly, unnecessary, unprofessional looking grey background layer behind "1 Executive Summary" for no discernible reason that'd sink any pitch [2].

Yes, professional decks don't all have extensive, unnecessary, overly branded multicoloured graphs that provide little useful information and I do view those as a blight against readability myself.

But professional decks also rarely if ever should contain artefacts from slap-dash execution like this example does. The GPT-6.2 Astra result is inferior to its own predecessor in the labs own example, simple as that.

[0] https://imgur.com/a/yRwNy6q

[1] https://imgur.com/a/L41WaW3

[2] https://imgur.com/a/MDWUutw

infecto 4d ago on HN
Going to have to disagree mostly. The text in your better example is garbage and reads like AI slop. Slight agree some of the design nits could be true but the content is objectively better.

And again your nits don’t align with a lot of important decks getting put together. It’s not that it’s invalid but the examples they have show much stronger language that reads more like what an analyst/associate would put together and good decks often have stark design choices like gray rectangles.

agar 4d ago on HN
As a former banker, hard disagree. In banking, content is everything and design is secondary (as long as the formatting itself is consistent).

Besides the AI-isms in the headings, the 6.0 example uses meaningless words and makes unactionable and vague recommendations. What is growth on a "directional" basis (growth is already directional)? Where is the value-add in "convert visits into larger baskets"? Compare to 6.2's "ugly arrow" recommendations that are actionable, if not insightful.

Worse, 6.0 seems to conflate "traffic" with "transactions," when they are hugely different things.

And no, I will not give the "AI-isms" a pass. Execs and boards approve paying a banker (potentially) millions of dollars in fees for their insight and advice; having analysis so obviously outsourced to AI would kill credibility far far faster than the grey background layer you claim would "sink any pitch."

infecto 4d ago on HN
+1. PE here and same point. Everyone has their own little styling standards but the best decks are the simplest to look at. Pictures only exist for headshots and product maps. Lots of boring boxes with concise text wins everyday.
Foobar8568 4d ago on HN
What do you think of them in comparison to the Hy4 examples? https://hy.tencent.ai/research/hy4
agar 4d ago on HN
The most relevant Hy4 example seemed to be a research report, which is from a different division (generally) than banking (rules limiting info bleed between research and banking are complex). A research report has different objectives than an investment banking pitch deck, as well as a different format. So they're not really comps (that's a subtle banking joke there, haha).

That said, not a fan. A bit better than the 6.0 pitch deck, but not something I'd be comfortable sending to institutional investors without a solid rewriting pass.

butlike 3d ago on HN
Is that swirly building a real building?!
Topfi 3d ago on HN
Having read both rather than skimming, yeah, I very much agree, the writing is utter none sense and much easier to parse, plus actually accurate in the 6.2 Astra example.

Thing is, was 6.0 Astra this truly unusable in providing simple boiler plate in such a task? 6.0 Astra output never read good to me, but was the prior gen truly so unusable that this is a leap to shout from the rooftops? Having used both, do you see a leap in this regard?

I will admit that after I saw the greyish rectangle in the top right corner of the 6.2 example, I got a bit blinded to the writing flaws in the 6.0 example. Add to that my very bad first run experience with the model, was not fully looking at these objectively. Will step back and just run evals for the week, like usual.

Still feel some improvements in the shown examples seem like stuff that the prior model gen should already have been capable off.

nl 4d ago on HN
The Astra 6 example [0] reads much worse than [1].

That "ex-Refund measures are review calculations" reads as pure slop. What does that even mean?

Topfi 4d ago on HN
Will happily admit I missed that one, that is truly awful. Guessing it's supposed to refer to figures without tariff refunds, but not sure to be honest.

I will however at this stage also have to defend GPT-6 Astra. No, I'd never use any model writing from GPT-6 Astra (and doubt 6.2 will change that) in a presentation or documentation, but I have never read that model be this unintelligible. If going from that worst case to slightly less bad is worthy of celebrating in the announcement, I am still very unconvinced on the office work front.

torginus 3d ago on HN
Every presentation I've held for senior management has been a shitshow. It usually goes like this: I show the first slide with actual data on it, Clevel comments, that this is not the data he's looking for, but something else.

Then I remember I also have that, so I quickly jump to slide 15, then he asks the next question, which I have no slide for, so I pull up Grafana, and plot him the data, while my buddy speaks about stuff etc. etc.

Having AI generate these slides without me knowing whats in them and why would be suicidal.

That is, if I present to people who actually care about what I'm presenting. These boring slide decks most people sleep through are of no consequence. But it seems the nature of the game didn't change - AI generates slop thats' only good for saving me time and wasting it for others.

Topfi 3d ago on HN
Strongly agreed on all fronts given experience in a prior org, though I can nowadays say with confidence, there are still places with senior management that trust that you will provide the data and tend to give you the space to present before asking follow-ups. Am grateful for that, know it's unfortunately very rare.
drob518 3d ago on HN
You should never get in front of senior management with a slide deck you don’t understand, whether the slides were made by AI or your coworker. As a former exec, I’ll say that it’s also OK to start a presentation by saying, “Here’s what we’re going to go over… Is there anything you specifically want me to zoom in on so we don’t waste time?” Then, let the exec answer and focus on getting that information out right at the start. If an exec gets mad at you for asking, find another company or at least group in the company. The worst presentations are when someone has prepared 50 slides of dry, dense, exhaustive numbers for a 30 minute update and is determined to go through them linearly and completely just because they think this is their 15 minutes of fame in front of senior management. Don’t be afraid to ask for direction and then leave or email your deck to people if they want all the numbers. And none of that has anything to do with AI. In general, with senior management, time is precious, so less is more, and at any given time they are most concerned with a limited number of focus things. As for the rest, they just want to be assured that nothing is on fire.
LazyGooze 3d ago on HN
corporate bleak or office aestetic, clean but bland and tasteless...
drob518 3d ago on HN
Pretty much par for the course of corporate decks.
Foobar8568 4d ago on HN
When hy4 was published, it was packed with valuation exemples, when I checked them, plenty of errors (or not,not in the field) but they looked sound and actually researched, most likely helped from their investment companies. OpenAI looked … shallower? I didn’t feel inclined to check more, I am not in that field so I truly can’t comments, but I wasn’t impressed.
KoolKat23 4d ago on HN
Yes, folks need to remember what powers Microsoft Copilot.
Topfi 3d ago on HN
The 5.6 Sol example was because I had to assist someone with getting Copilot to work as well as it could. Was my first experience of Copilot in a while where steering the model was somewhat crucial.

It did not lead to any misplaced labels or visual artifacts (which I'll maintain is embarrassing in a launch post) but purely subjectively, not at all based on data, I felt like 5.6 Sol in Copilot behaved less consistently vs Codex for similar work. Maybe it is hamstrung by the additions, system prompt, tooling, etc. that Copilot as a harness ships with, don't know.

Could be completely wrong, but have felt for a long time that the approach taken by Copilot is not long for a world in which any schmuck can leverage PptxGenJS and the like without even realizing it. Makes the integration into the Copilot365 suite of office tools less valuable.

KoolKat23 3d ago on HN
Absolutely Microsoft Copilot's implementation is inferior.

My point is more on the presentations and excel etc. There is a significant userbase outside the software and marketing world, where function over form matters. It makes sense it's being led in a certain direction, there is a significant userbase there, just indirect.

conception 4d ago on HN
Similarly doing page/book layout is really basic and starting template like compared to Claude.

The writing is much better though. Still sloppish but at least recognizable as language.

matchagaucho 4d ago on HN
6.2 seems optimized for benchmarks. Not creative.

After a couple hours of testing, we reverted back to 6.1 for basic document generation, proposals, marketing content.

tech_army 4d ago on HN
Ye same. Didn’t impress me
tonfreed 3d ago on HN
Having my first good go of Sol 6.2 today, it's asking for permission on the stupidest things. I have an explicit request edit mode call in my harness, it called it twice, was approved twice and told so by the tool, then said "read only reaffirmed, I'm stopping here". I told it I want to add both dev and test changes in a single PR since the prod changes aren't going to be active, it created both the changes but only pushed the dev changes.

Not a fan of this thing. It's wasting a lot of time today.

evannotfound 2d ago on HN
The same thing happened to me. It keeps saying that it is in plan mode even though I had already switched to build. seems like it ignores part of the instructions/conversation history.
tonfreed 30h ago on HN
Only comparable thing I've seen elsewhere is DeepSeek trying to conform to a non-existent turn budget. Even that was easy to deal with by modifying my system prompt.
xg15 3d ago on HN
Recently was looking up some details on their API page and asked their on-page chatbot for help. The chatbot produced a good summary with some links to other pages in the apidoc.

Clicking on a link navigated to it in the same browser tab and erased the chatbot conversation.

Apparently the conversation was only stored in the loaded page DOM and not persisted anywhere, so when navigating away, it was just gone...

On the one hand, "next stage of humanity", on the other hand, stuff like that...

tech234a 4d ago on HN
Tweeted 11 minutes ago https://x.com/OpenAI/status/2122750124543926515, posted to HN 18 minutes ago
DavCreator 4d ago on HN
zb3 4d ago on HN
> we’re launching GPT‑6.2 Astra and Sol with tighter safeguards for higher-risk cybersecurity assistance

Seems they really want these "safeguards" to be as ridiculous as those of Claude..

I_am_tiberius 4d ago on HN
No reset?
rcr-anti 4d ago on HN
Odd, doesn't look like they're available on the cloud providers, only first party. Not a single mention of Azure or AWS.
voidmain0001 4d ago on HN
I hope the video advertisement on that page was made with ChatGPT and a video plug-in otherwise if it wasn't then what's the point of Astra and Sol?
onlyrealcuzzo 4d ago on HN
TL;DR - from the little I could gather, Sol 6.2 looks particularly impressive.

But... is it just me, or does this product launch page look like AI Slop?

https://www.vals.ai/comparison?m=claude-fable-5-2,gpt-6.2-as... seems like a better comparison than what I could get from their page.

Astra is ~20% slower, ~40% cheaper, and a bit less powerful than Fable. Sol remains way cheaper than anything remotely in the same league, and it's speed to complete tasks seems to have improved considerably.

Scrolling through it has the same hypnotizing effect of trying to read anything written by LLMs.

It seems like things that should make sense, then I try to look at the charts and a lot of them are comically unreadable.

I tried interacting with some of the examples, and the Lamp Builder - for example - I couldn't even figure out what it's trying to show or what I'm supposed to do - or why I should be impressed.

suddenlybananas 4d ago on HN
I wouldn't go as far as to call this slop but the lamp builder thing was super weird and unclear for me too! Even clicking the other tab cause my browser to scroll down a lot which I found very jarring.
munksbeer 4d ago on HN
Are they intentionally lowering the cost of these models to the extreme, because of the Anthropic IPO? This just seems insane?
minimaxir 4d ago on HN
The entire industry is lowering costs, not just OpenAI/Anthropic, both due to a) open-weight model pressure and b) genuine efficiencies. Per-token profit margins are large enough to allow price competitions.

https://news.ycombinator.com/item?id=50236102

mrandish 4d ago on HN
Recently, I've complained about OpenAI (and other tech company's) product landing pages communicating virtually no useful information about what the product is or why it might useful. So, I have to concede this is at least a step in the right direction.
jrflo 4d ago on HN
Looks like a great efficiency gain.

What caught my attention was the bit in the Alignment section:

> Both models performed similarly to GPT-6 Astra on most alignment evaluations, and took fewer improper actions in simulated workplace tasks. However, in two tests, they were more likely to omit mentioning obstacles that blocked their work, such as a missing file or unavailable search tool. We added instructions in Codex that substantially reduce these omissions, and we’re continuing to investigate the behavior.

So the models are inherently less transparent, unless you ask them to be more transparent? Seems like a band-aid solution...

HyperL0gi 4d ago on HN
My company can only hold one subscription per employee, and I still can't find a reason to go back to OpenAI after migrating to Claude once Opus 5.5 was released. It's super efficient, I almost never run out of tokens with the Teams Premium seat, and Fable is fantastic. They lost me when Astra was released and tokens simply evaporated with a few prompts.
firemelt 4d ago on HN
ehat effort do you use ur opus5.5?
anentropic 4d ago on HN
Medium just works for most stuff
Robdel12 4d ago on HN
Nice! I still use GPT-6 luna for a ton of stuff, it's super solid (for me). So I hope there's a little bump for that model, too, soon
sreekanth850 4d ago on HN
So they release 6.2 just before Anthropic IPO.
ImJasonH 4d ago on HN
500 | Internal Server Error
simonw 4d ago on HN
Pelicans for 6.2 Sol: https://tools.simonwillison.net/markdown-svg-renderer?url=ht...

And for 6.2 Astra: https://tools.simonwillison.net/markdown-svg-renderer?url=ht...

Here's an updated comparison grid for the entire GPT-6 family: https://static.simonwillison.net/static/2026/openai-pelicans...

UPDATE: And if you're bored of pelicans, here's what I got for:

> Make a three js animation where yonkers stands up as a big mech (cool stand up motion) and stomps around manhattan and queens and Brooklyn, use openstreetmap mapping data

6.2 Astra (Ultra in Codex): https://static.simonwillison.net/static/2026/yonkers-gpt-6.2...

6.2 Sol (Ultra in Codex): https://static.simonwillison.net/static/2026/yonkers-gpt-6.2...

For comparison, here's Fable 5.2 Medium: https://tools.simonwillison.net/yonkers-rises and Gemini 4 Carbon: https://static.simonwillison.net/static/2026/yonkers-mech-st...

p11p 4d ago on HN
Are you getting any signal out of this anymore? All I can see is "good pelican" and "dogshit pelican". These ones look pretty good.
EugeneOZ 4d ago on HN
I do. 6.2 Sol xhigh and max show the results comparable to Astra 6 max, and Astra 6.2 only shows any improvement on "max" reasoning effort level.
adverbly 4d ago on HN
You're kidding right?

These are some of the worst pelicans I've seen in a while.

Pay attention to the stacking layers near the legs. Sol literally never got it right, and Astra regressed on it multiple times...

Also what is that bending bar from Astra?

jay_kyburz 4d ago on HN
When are the Pelicans going to stop being rendered 2d like a child's drawing. We are a million miles away from what a professional artist would come up with.

Update: Here is some Bluey characters riding bikes as a reminder how far these models have to go.

https://www.bluey.tv/characters/uncle-rad/

Hacktrick 4d ago on HN
I'm not sure if this is a useful benchmark any longer
InsideOutSanta 4d ago on HN
They're extremely useful. In fact, I refuse to make infrastructure decisions in a pelican-blind environment.
EugeneOZ 4d ago on HN
still the best benchmark! thanks
firemelt 4d ago on HN
any index link for all ur pelicans i want to see fable and opus
tintor 4d ago on HN
Sol 6.2 max is still failing on pelican benchmark. Left leg is jammed in chain.

Astra 6.2 max did a similar mistake on the left bicycle pedal.

frangonf 4d ago on HN
But Astra 6.2 low and medium didn't make this mistake.
BoldColdHold 4d ago on HN
Wow the yellow is leaking into their llms too.
vopi 4d ago on HN
This might be in other pelicans, but 6.2 Sol/Astra is the first time I'm noticing a model shade the leg further in the frame darker to mimic depth (or a shadow).

It's also interesting you can clearly tell 6.2 Astra does a much better job of the above. 6.2 Sol attempts it at higher reasoning levels, but it's crude in comparison.

I wonder if it comes from the (seemingly) recent inclusion of 3D environments in training data.

I_Write_It 4d ago on HN
They all seem very good, with a lot of attention in detail ! Thx for the Pelicans!
adverbly 4d ago on HN
What's with everyone saying these Pelicans are great?

These are some of the worst regressions that I've seen in a while.

Pay close attention to the stacking layers around the feet, pedals (sometimes there aren't even two pedals), wheel, and two legs. Some pretty obvious mistakes in most if not all of these...

Edit: And what's up with the single arm on the two highest Astra images?

edit2: really? I'm getting downvoted because people don't like that I pointed out a mistake in a Pelican svg? Is that where we're at?

svachalek 4d ago on HN
The highest Astra images give the pelicans wings instead of arms, which does seem like a valid interpretation.
adverbly 4d ago on HN
Do you mean on X-High where its got both legs on one side of the frame?

Or on Max where its for some reason only using its left arm/wing - which looks totally different from its right arm/wing - and is grabbing the right side of the handlebar with its left hand for some reason?

Look. I think at first glance these look pretty good. I'd be astounded with this level of quality a few years ago.

But people saying that this benchmark is done are completely missing the point that accuracy, consistency, and details matter.

I'm not willing to say this benchmark is done until I see consistent and accurate details.

preommr 4d ago on HN
I have to agree, those results are surprisingly bad and I am not seeing an improvement.

For sol 6.2, some of them are slightly better at higher cost, some of them are way worse and only slightly cheaper (but comparable to terra in quality while being more expensive).

I guess we'll see as more information comes out, but so far not looking good.

foltik 4d ago on HN
It’s a recurring theme with all of these generative models. The images, UIs, music, code, prose, etc. that they produce all seem high quality, but only if you squint.

Quick glance at the table, wow pelican benchmark is solved! Oneshot a complex web app, wow software engineering is solved!

Of course upon closer inspection it’s always an incoherent mess. A poor imitation (i.e. lossy compression) of quality.

RGS1811 4d ago on HN
The emergence of the beach setting and the scarf is interesting.
kzrdude 4d ago on HN
I think a scarf or similar is relatively common with bicycle cartoons, to indicate speed or movement.
globular-toast 4d ago on HN
Do we know why they always end with a scarf?
pinkyclouds2 4d ago on HN
winter is coming
phoghed 4d ago on HN
They are a classic motif for pilots, birds fly, and there are famous cartoon birds with a scarf, like the ones from The Rescuers or Duck Tales come to mind.
ryanschaefer 4d ago on HN
I think this is the first time I’d call the pelican benchmark solved. All levels of effort look good.
prmoustache 4d ago on HN
Pelican is one legged on gpt 6.2 sol below high and has both legs on same side of the bicycle on high.
arcastroe 4d ago on HN
one defect I noticed is that the back leg still bends a different direction than the front leg in many of those images. In both Astra and Sol.

Something a human can recognize as inconsistent, but not the SOTA leading frontier model.

gibspaulding 4d ago on HN
I find it somewhat amusing that it can’t quite decide which way the legs should bend since it actually is pretty debatable. Birds knees bend the opposite way ours do (technically it’s their ankle, but it’s what you’re looking at here), it just looks bizarre to draw something like that in a bike.

https://en.wikipedia.org/wiki/File:American_White_Pelican.jp...

Melatonic 4d ago on HN
Maybe the next models will train on these comments and change the bicycle design itself to better fit how a Pelicans legs would locomote
lukevp 4d ago on HN
But is the model given the visual and an attempt to iterate? If I sat you down at a keyboard and asked you to write raw SVG code would you be able to draw a pelican? That’s the evaluation, not the analysis of the resulting image.
TiredOfLife 4d ago on HN
You need Sol at minimum xhigh to get 2 legs.

While Astra only low looks good to me.

boutell 4d ago on HN
Interesting that pelican quality does not go up monotonically within Astra. Honestly, I think low was the best one.
glenjamin 4d ago on HN
Interestingly, on the mech thing it seems like only Fable really nailed the brief - the others might look cooler, but Yonkers and the mech aren't directly connected in the same way.
boutell 4d ago on HN
Fable gets at the mech Yonkers idea in a much more entertaining way than the others.
prescriptivist 4d ago on HN
Turning Beech Hill into shoulder mounted cannons is pretty clever.
BrokenCogs 4d ago on HN
No idea what a yonkers is but that fable 5.2 animation blows the gpt 6.2 models out of the water
dllu 4d ago on HN
Pelicans still not saturated. No chain or front fork offset, and Astra added a rather disconnected detail on top of the pelican's head. Still, we've come a long way since the early days. Very exciting for the future of pelican cyclists!
fekunde 4d ago on HN
Wow, surprisingly Gemini 4 Carbon really nailed the Yonkers prompt. I like how the sections of Yonkers held shape in the mech. Fable tried but gemini is more detailed.
iandanforth 4d ago on HN
It did not. A robot appears and then bits of a map stick to it. Only Fable did well.
Closi 4d ago on HN
Agree Fable did 'best' (most accurate, most consistent), but Gemini had the most style and was probably the coolest, and GPT did the worst by far.
okrad 4d ago on HN
Looks like high/xhigh both get the back leg z-index incorrect relative to the back wheel of the bike and frame.
DenisM 4d ago on HN
The frame/leg problem was discussed here previously and likely trickled into the training set.

The problem you pointed out was never discussed on hacker news, and it clearly shows they still lack spatial reasoning. I wish you didn’t mention it. :)

clzerv 4d ago on HN
The Fable5.2 version is the only one that allows user interaction with the model, it's also very clean and minimal. I've been using Sol-5.1-high for a dumb web project and it tends to create really baroque code and UIs. I haven't used Claude in a while and this makes me want to try it again.

It seems like the models have a kind of built in aesthetic sense and I wonder what part of the training influences this. Maybe if more RL time was spent on artistic tasks the models could not only make better visuals but also code.

Currently they all seem to care little about code quality and maintainability (by humans), just functionality, which is fine I guess if you can expect to vibe code forever. But what if there is a critical bug and the models are temporarily unavailable for some reason? It would be hopeless to expect a human to wade through the giant bowl of clanker soup and fix it anytime soon.

zapkyeskrill 4d ago on HN
Astra xhigh .. so not quite ready to take over the world then.
Melatonic 4d ago on HN
Odd that the smartest Astra starts making the left arm/wing drive the bike with the right side (toward us) facing backwards like a bird would normally look
zf00002 4d ago on HN
is this finally their answer to opus 5.5?
thimabi 4d ago on HN
This release promises three things that I am pretty excited for:

- better writing

- better 3D work

- better design for documents and presentations

If OpenAI really managed to get all these things while keeping costs down, then using these models, particularly 6.2 Sol, will be a no-brainer for me. I must say, however, that the slide samples shown on the website are a bit bland and disappointing.

jrflo 4d ago on HN
Opus has far better design tastes IMO, and is already great at 3D work
derac 4d ago on HN
This comes off as very partisan when you're commenting on a model that is minutes old that you haven't used.
jrflo 4d ago on HN
Sorry I should’ve clarified, I’m commenting on the previous version
lexh 4d ago on HN
Before the pelicanistas arrive, allow me to present pelican-zapper:

https://github.com/lexh/pelican-zapper

It’s a small browser extension that automatically collapses pelican-related threads on HN, a local balm for the memetic nightmare affecting approximately 100% of model-release stories.

gpugreg 4d ago on HN
Alternatively, here is a uBlock Origin one-liner that hides comments that contain the word pelican (also includes our comments)

    news.ycombinator.com##tr.comtr:has(.commtext:has-text(/\bpelicans?\b/i)) .comment:style(display: none !important;)
lexh 3d ago on HN
Yes! Mine just collapses the entire subthread and plays nice with the existing affordance. But yeah, can't beat a one-liner.
firemelt 4d ago on HN
do astra or fable that have better html ui frontend design?
gpugreg 4d ago on HN
The first graph (Agents' Last Exam v1.1) clearly got mangled by the marketing department so you can't read the cost of most models. Here is a version with a logarithmic horizontal axis:

https://asdf10.com/gpt-6.2_agents-last-exam.svg

I also changed the vertical axis to start at 0 instead of 60%. One might argue that it uses less of the vertical screen real estate, but it is more honest because it shows there is little difference between the scores of the compared models.

claiir 4d ago on HN
> Due to their increased capabilities, we’re launching GPT‑6.2 Astra and Sol with tighter safeguards for higher-risk cybersecurity assistance.

This is unfortunate—that was one of the big advantages of Astra.

jeffbee 4d ago on HN
I can't even get 6.1 Sol to summarize the log of my own fuzzing fixture running on my own project. I have to use Gemini models to handle my fuzzing tasks. It's ridiculous.
claiir 4d ago on HN
Ran into a false positive within the first two minutes of using 6.2 Astra.
popcar2 4d ago on HN
I know the video is a comedy but it's so tone deaf that they're advertising it as "you should lie to your boss and make the AI do your job!"

I'm sure for investors they can make an opposite version of that ad, "you should fire all your employees and make the AI do it! They're not doing anything anyways!"

red369 4d ago on HN
My first thought is in the same category - it's just an amusing ad, but I notice in ad-land they didn't have to worry about "AI-generated content may be incorrect" disclaimers
jorl17 4d ago on HN
I really want GPT models to be good, but Sol models are so slow I cannot use them. Maybe the 500$ subscription (or enterprise packages) are better, but it is unbearably slow. I've tried the fast variant and low reasoning levels and there isn't a significant improvement.

Couple that with the lack of reasoning traces, and I cannot even have a clue what the model is doing while it is working. This is perfectly fine for when we are developing with care for the code (in which case I will know what it is doing by reviewing the output), but not for purely vibe-coding scenarios. And the thing is....if I care about the code...I'd rather trust Opus or Fable.

ativzzz 4d ago on HN
Does speed really matter? Most of the time I get the AI to do something, I immediately switch to another one of my things I have in progress and then come back at some point later. I'm never sitting there waiting for it to finish

Showing 400 of 864. Read the rest on Hacker News

Comments are loaded live from Hacker News and are not stored by Mid or Real.